The Developing AI-Enabled Database Solutions (DP-800)
Passing Microsoft Microsoft Certified: SQL AI Developer exam ensures for the successful candidate a powerful array of professional and personal benefits. The first and the foremost benefit comes with a global recognition that validates your knowledge and skills, making possible your entry into any organization of your choice.
DP-800 Exam Dumps
- Exam Code: DP-800
- Vendor: Microsoft
- Certifications: Microsoft Certified: SQL AI Developer
- Exam Name: Developing AI-Enabled Database Solutions
Why CertAchieve is Better than Standard DP-800 Dumps
In 2026, Microsoft uses variable topologies. Basic dumps will fail you.
| Quality Standard | Generic Dump Sites | CertAchieve Premium Prep |
|---|---|---|
| Technical Explanation | None (Answer Key Only) | Step-by-Step Expert Rationales |
| Syllabus Coverage | Often Outdated (v1.0) | 2026 Updated (Latest Syllabus) |
| Scenario Mastery | Blind Memorization | Conceptual Logic & Troubleshooting |
| Instructor Access | No Post-Sale Support | 24/7 Professional Help |
Customers Passed Exams
10
Success backed by proven exam prep tools
Questions Came Word for Word
90%
Real exam match rate reported by verified users
Average Score in Real Testing Centre
87%
Consistently high performance across certifications
Study Time Saved With CertAchieve
60%
Efficient prep that reduces study hours significantly
Coverage of Official Microsoft DP-800 Exam Domains
Our curriculum is meticulously mapped to the Microsoft official blueprint.
Design and Develop Database Solutions (40%)
Master the architecture of AI-enabled databases. Includes designing constraints, partitioning strategies, and implementing advanced programmability objects like stored procedures and triggers. A key 2026 focus is AI-assisted authoring, utilizing GitHub Copilot to generate and optimize complex T-SQL code.
Secure, Optimize, and Deploy Database Solutions (40%)
Expertise in enterprise-grade production environments. Mastering passwordless authentication, auditing, and securing GraphQL or REST endpoints. Includes implementing modern DevOps for data through CI/CD pipelines using SQL Database Projects and optimizing query performance for high-concurrency AI workloads.
Implement AI Capabilities in Database Solutions (30%)
The core of the 2026 update. Mastering the technical implementation of Retrieval-Augmented Generation (RAG) and Semantic Search. Expertise in handling Vector data types, generating embeddings via T-SQL, and using sp_invoke_external_rest_endpoint to integrate Azure OpenAI directly into the database layer.
Microsoft DP-800 Exam Domains Q&A
Certified instructors verify every question for 100% accuracy, providing detailed, step-by-step explanations for each.
Question 1
Microsoft DP-800
QUESTION DESCRIPTION:
You have an Azure SQL database named SalesDB on a logical server named sales-sql01.
You have an Azure App Service web app named OrderApi that connects to SalesDB by using SQL authentication.
You enable a user-assigned managed identity named OrderApi-Id for OrderApi.
You need to configure OrderApi to connect to SalesDB by using Microsoft Entra authentication. The managed identity must have read and write permissions to SalesDB.
Which Transact-SQL statements should you run in SalesDB?
Correct Answer & Rationale:
Answer: C
Explanation:
For an Azure App Service using a user-assigned managed identity to connect to Azure SQL Database with Microsoft Entra authentication , the required database-side step is to create a database user from the external provider , then grant the needed database roles. Microsoft’s Azure SQL documentation for managed identities states that to let a managed identity access the target database, you create a SQL user for that identity by using:
CREATE USER [ < identity-name > ] FROM EXTERNAL PROVIDER;
and then assign the appropriate roles.
That makes db_datareader and db_datawriter the right role grants here, because the requirement says the identity must have read and write permissions to SalesDB.
The other options are incorrect:
A uses CREATE LOGIN ... FROM EXTERNAL PROVIDER, which is not the right choice for this Azure SQL Database scenario; the documented pattern is to create a database user from the external provider.
B and D create SQL-authentication principals with passwords, which does not meet the Microsoft Entra managed-identity requirement.
D also grants sysadmin, which is a server-level overgrant and not appropriate for the stated read/write requirement.
Question 2
Microsoft DP-800
QUESTION DESCRIPTION:
You have an Azure SQL database that contains tables named dbo.ProduetDocs and dbo.ProductuocsEnbeddings. dbo.ProductOocs contains product documentation and the following columns:
• Docld (int)
• Title (nvdrchdr(200))
• Body (nvarthar(max))
• LastHodified (datetime2)
The documentation is edited throughout the day. dbo.ProductDocsEabeddings contains the following columns:
• Dotid (int)
• ChunkOrder (int)
• ChunkText (nvarchar(aax))
• Embedding (vector(1536))
The current embedding pipeline runs once per night
Vou need to ensure that embeddings are updated every time the underlying documentation content changes The solution must NOT ' equire a nightly batch process.
What should you include in the solution?
Correct Answer & Rationale:
Answer: D
Explanation:
The requirement is to ensure embeddings are updated every time the underlying content changes without relying on a nightly batch job. The right design is to enable change tracking on the source table so an external process can identify which rows changed and regenerate embeddings only for those rows. Microsoft documents that change detection mechanisms are used to pick up new and updated rows incrementally , which is the right pattern when you need near-continuous refresh instead of full nightly rebuilds.
This is better than:
A. fixed-size chunking , which affects chunk strategy but not change detection.
B. a smaller embedding model , which affects model cost/latency but not update triggering.
C. table triggers , which would push embedding-maintenance logic directly into write operations and is generally not the best design for AI-processing pipelines. The question specifically asks for a solution that replaces the nightly batch requirement, not one that performs heavyweight work inline during every transaction.
Question 3
Microsoft DP-800
QUESTION DESCRIPTION:
You have an Azure SQL table that contains the following data.
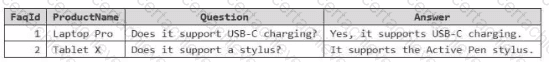
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
A)
B)
C)
D)
Correct Answer & Rationale:
Answer: A
Explanation:
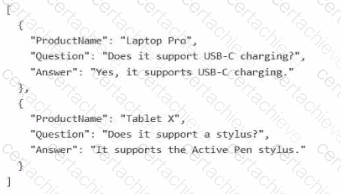
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
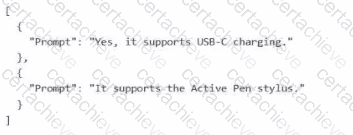
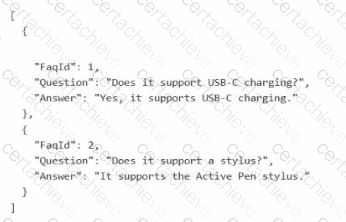
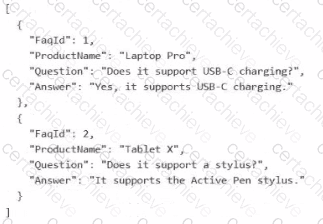
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
Option A keeps the meaningful text fields and removes the low-value identifier.
Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
Question 4
Microsoft DP-800
QUESTION DESCRIPTION:
You have an Azure SQL database that contains a column named Notes.
A security review discovers that Notes contains sensitive data.
You need to ensure that the data is protected so that neither the stored values nor the query inputs reveal information about the actual data. The solution must prevent a user from inferring relationships or repetitions in the data based on the encrypted output
Which should you use?
Correct Answer & Rationale:
Answer: B
Explanation:
The requirement says the stored values and query inputs must both be protected, and users must not be able to infer relationships or repetitions in the data from the encrypted output. Microsoft documents that deterministic encryption always produces the same ciphertext for the same plaintext , which allows equality comparisons but also leaks patterns. By contrast, randomized encryption produces a different encrypted value each time for the same plaintext, which improves security and prevents pattern analysis based on repeated ciphertext values.
That makes randomized encryption the right choice here:
It protects data at rest and in transit/query parameters under Always Encrypted’s client-side encryption model.
It prevents attackers from learning that the same plaintext value appears repeatedly, because repeated inputs do not produce repeated ciphertext.
Why the other options are wrong:
A. Always Encrypted with secure enclaves adds richer confidential query support, but the key protection property the question is testing is the encryption type. The requirement to prevent inference from repeated ciphertext points specifically to randomized encryption .
C. RLS controls row access, not value confidentiality.
D. Deterministic encryption allows equality-based operations but leaks repetition patterns, which the question explicitly forbids.
Question 5
Microsoft DP-800
QUESTION DESCRIPTION:
You have an Azure SQL database that supports the OLTP workload of an order-processing application.
During a 10-minute incident window, you run a dynamic management view query and discover the following:
Session 72 is sleeping with open_transaction_count = 1.
Multiple other sessions show blocking_session_id = 72 in sys.dm_exec_requests.
sys.dm_exec_input_buffer(72, NULL) returns only BEGIN TRANSACTION UPDATE Sales.Orders.
Users report that updates to Sales.Orders intermittently time out during the incident window. The timeouts stop only after you manually terminate session 72.
What is a possible cause of the blocking?
Correct Answer & Rationale:
Answer: C
Explanation:
The best explanation is an open explicit transaction . During the incident, session 72 was sleeping but still had open_transaction_count = 1 , and sys.dm_exec_input_buffer(72, NULL) showed only BEGIN TRANSACTION UPDATE Sales.Orders. That pattern indicates the session executed an update inside an explicit transaction and then remained idle without committing or rolling back , while still holding locks. Other sessions showing blocking_session_id = 72 is the expected symptom of that situation. Microsoft explains that blocking occurs when one session holds a lock on a resource and another session requests a conflicting lock, and sleeping sessions can continue to block if they retain locks through an open transaction.
This also fits the observed behavior that the timeouts stopped only after session 72 was terminated . Killing the session would roll back the active transaction and release the locks, allowing waiting updates to continue. That is much more consistent with an uncommitted transaction than with a deadlock, because deadlocks are normally detected and one session is chosen as the victim automatically rather than persisting until manual termination.
Question 6
Microsoft DP-800
QUESTION DESCRIPTION:
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Correct Answer & Rationale:
Answer: D
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector(1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
A would require manual comparison logic and would increase latency rather than minimize it.
B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft’s current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam-aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
Question 7
Microsoft DP-800
QUESTION DESCRIPTION:
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Correct Answer & Rationale:
Answer: B
Explanation:
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content , not simple categorical, numeric, or location-only values. Microsoft’s DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings , generating embeddings , and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches.
In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location . Those are descriptive context elements that are typically captured in a free-text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search , semantic search , and RAG retrieval . Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items.
The other options are weaker choices:
vehicleLocation is too narrow and usually better handled with geospatial filtering , not embeddings.
incidentType is likely categorical and too low in semantic richness.
SeverityScore is numeric and not appropriate as the primary source for semantic embeddings.
Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding. But among the options given, the best and most exam-aligned answer is the textual narrative column : incidentDescrlption .
Question 8
Microsoft DP-800
QUESTION DESCRIPTION:
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
Correct Answer & Rationale:
Answer: D, E
Explanation:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft’s JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design. Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam-consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Question 9
Microsoft DP-800
QUESTION DESCRIPTION:
You need to recommend a solution to lesolve the slow dashboard query issue. What should you recommend?
Correct Answer & Rationale:
Answer: B
Explanation:
The best recommendation is B because the slow query filters on FleetId and returns LastUpdatedUtc , EngineStatus , and BatteryHealth . A nonclustered index with FleetId as the key column allows the optimizer to perform an index seek instead of a clustered index scan, and including the other selected columns makes the index covering , which reduces extra lookups and I/O. Microsoft’s SQL Server indexing guidance states that a nonclustered index with included columns can significantly improve performance when all query columns are available in the index, because the optimizer can satisfy the query directly from the index.
The query is:
SELECT VehicleId, LastUpdatedUtc, EngineStatus, BatteryHealth
FROM dbo.VehicleHealthSummary
WHERE FleetId = @FleetId
ORDER BY LastUpdatedUtc DESC;
Among the given choices, FleetId is the most important search argument because it appears in the WHERE predicate. Microsoft’s index design guidance recommends putting columns used for searching in the key and using nonkey included columns to cover the rest of the query efficiently.
Why the other options are weaker:
A is not appropriate because changing the clustered index to LastUpdatedUtc would not target the main filter predicate on FleetId, and a table can have only one clustered index.
C makes LastUpdatedUtc the key, which is poor for a query whose primary filter is FleetId.
D is not the right answer here because the query requirement does not specify only recent rows, and filtered indexes are meant for a well-defined subset; this option also uses a time-based expression that is not aligned to the stated query pattern.
Strictly speaking, the most optimal design for both filtering and ordering would usually be a composite key like (FleetId, LastUpdatedUtc), but since that is not one of the available options, B is the correct exam answer.
Question 10
Microsoft DP-800
QUESTION DESCRIPTION:
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements.
What should you include in the recommendation?
Correct Answer & Rationale:
Answer: C
Explanation:
The best recommendation is to use an MCP server . In the official DP-800 study guide , Microsoft explicitly lists skills such as configuring Model Context Protocol (MCP) tool options in a GitHub Copilot session and connecting to MCP server endpoints, including Microsoft SQL Server and Fabric Lakehouse . That makes MCP the exam-aligned mechanism for enabling AI-assisted tools to work with live database context rather than static snapshots.
This also matches the stated development requirement: the team will use Visual Studio Code and GitHub Copilot and needs to retrieve live metadata from the databases . Microsoft’s documentation for GitHub Copilot with the MSSQL extension explains that Copilot works with an active database connection , provides schema-aware suggestions , supports chatting with a connected database, and adapts responses based on the current database context . Microsoft also documents MCP as the standard way for AI tools to connect to external systems and data sources through discoverable tools and endpoints.
The other options do not satisfy the “live metadata” requirement as well:
A .dacpac is a point-in-time schema artifact, not live metadata.
A Copilot instruction file provides guidance, not live database discovery.
Including the database project in the repository helps source control and deployment, but it still does not provide live database metadata by itself.
A Stepping Stone for Enhanced Career Opportunities
Your profile having Microsoft Certified: SQL AI Developer certification significantly enhances your credibility and marketability in all corners of the world. The best part is that your formal recognition pays you in terms of tangible career advancement. It helps you perform your desired job roles accompanied by a substantial increase in your regular income. Beyond the resume, your expertise imparts you confidence to act as a dependable professional to solve real-world business challenges.
Your success in Microsoft DP-800 certification exam makes your visible and relevant in the fast-evolving tech landscape. It proves a lifelong investment in your career that give you not only a competitive advantage over your non-certified peers but also makes you eligible for a further relevant exams in your domain.
What You Need to Ace Microsoft Exam DP-800
Achieving success in the DP-800 Microsoft exam requires a blending of clear understanding of all the exam topics, practical skills, and practice of the actual format. There's no room for cramming information, memorizing facts or dependence on a few significant exam topics. It means your readiness for exam needs you develop a comprehensive grasp on the syllabus that includes theoretical as well as practical command.
Here is a comprehensive strategy layout to secure peak performance in DP-800 certification exam:
- Develop a rock-solid theoretical clarity of the exam topics
- Begin with easier and more familiar topics of the exam syllabus
- Make sure your command on the fundamental concepts
- Focus your attention to understand why that matters
- Ensure hands-on practice as the exam tests your ability to apply knowledge
- Develop a study routine managing time because it can be a major time-sink if you are slow
- Find out a comprehensive and streamlined study resource for your help
Ensuring Outstanding Results in Exam DP-800!
In the backdrop of the above prep strategy for DP-800 Microsoft exam, your primary need is to find out a comprehensive study resource. It could otherwise be a daunting task to achieve exam success. The most important factor that must be kep in mind is make sure your reliance on a one particular resource instead of depending on multiple sources. It should be an all-inclusive resource that ensures conceptual explanations, hands-on practical exercises, and realistic assessment tools.
Certachieve: A Reliable All-inclusive Study Resource
Certachieve offers multiple study tools to do thorough and rewarding DP-800 exam prep. Here's an overview of Certachieve's toolkit:
Microsoft DP-800 PDF Study Guide
This premium guide contains a number of Microsoft DP-800 exam questions and answers that give you a full coverage of the exam syllabus in easy language. The information provided efficiently guides the candidate's focus to the most critical topics. The supportive explanations and examples build both the knowledge and the practical confidence of the exam candidates required to confidently pass the exam. The demo of Microsoft DP-800 study guide pdf free download is also available to examine the contents and quality of the study material.
Microsoft DP-800 Practice Exams
Practicing the exam DP-800 questions is one of the essential requirements of your exam preparation. To help you with this important task, Certachieve introduces Microsoft DP-800 Testing Engine to simulate multiple real exam-like tests. They are of enormous value for developing your grasp and understanding your strengths and weaknesses in exam preparation and make up deficiencies in time.
These comprehensive materials are engineered to streamline your preparation process, providing a direct and efficient path to mastering the exam's requirements.
Microsoft DP-800 exam dumps
These realistic dumps include the most significant questions that may be the part of your upcoming exam. Learning DP-800 exam dumps can increase not only your chances of success but can also award you an outstanding score.
The DP-800 Exam Questions explained hybrid database administration, migration strategies, and SQL Server concepts effectively. The PDF Questions and study guide were well organized and easy to follow.
Hannah Parker
Jun 6, 2026
Top Exams & Certification Providers
New & Trending
- New Released Exams
- Related Exam
- Hot Vendor